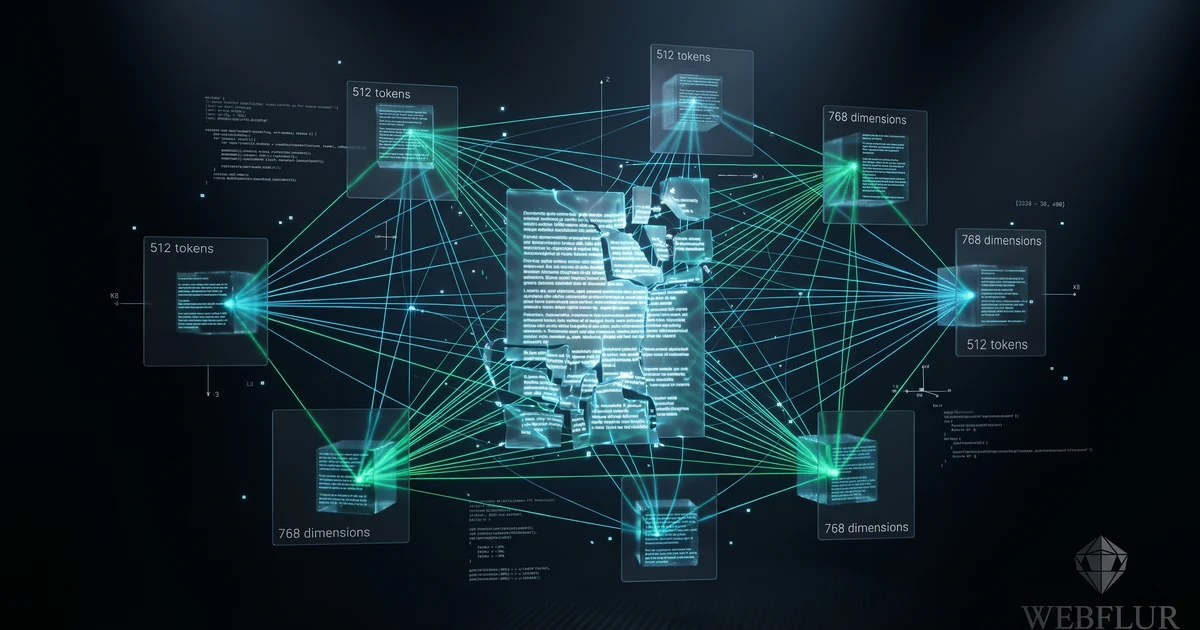
Content chunking for AI retrieval is the practice of structuring web pages into self-contained, semantically isolated 75–150 word passages that Retrieval-Augmented Generation (RAG) engines can cleanly extract without losing context. At WebFlur, our audits show that AI search models prioritize distinct, boundary-defined answer blocks over unstructured, multi-topic prose.
In August 2026, an enterprise DevOps orchestration platform approached us after shedding 34% of their non-branded organic traffic following the rollout of auto-expanding Google AI Overviews. Their technical documentation and architecture whitepapers were thorough — several exceeded 4,500 words — but every core insight sat trapped inside sprawling, 400-word paragraphs that braided prerequisite setup commands with runtime architecture explanations.
When we ran their pages through standard vector embedding simulations, the retrieval pass retrieved fractured fragments: an environment flag severed from its configuration file, or a security warning disconnected from its parent API endpoint. Meanwhile, an agile competitor with crisp, 95-word modular blocks and explicit heading boundaries was captured in 82% of category AI Overviews.
We restructured 22 of their top architectural pages into chunk-optimized blocks. Within 28 days, their citation frequency across Google AI Overviews and Perplexity surged from 11% to 54% without building a single new backlink.
What is content chunking for AI search?
Content chunking for AI search is the architectural discipline of dividing long-form content into autonomous logical units that retain complete meaning when isolated from the parent document. Traditional search engines index the entire URL as the primary ranking document, but modern generative search relies on passage-level retrieval where an AI model scores, vectorizes, and extracts discrete 100-word snippets.
Every web crawler feeding modern answer engines — whether it's OAI-SearchBot, PerplexityBot, or Google-Extended (the automated scraper that gathers data for Gemini) — parses text through a token-window splitter before passing vector embeddings into a retrieval index. When a user asks a complex question, the search engine doesn't feed your 3,000-word article into the language model's context window. It queries a vector database, identifies the top three or four passage chunks with the highest cosine similarity to the prompt, and hands only those fragments to the synthesizer.
If your explanation relies on context established four paragraphs earlier, the isolated chunk fails the LLM's factual grounding check and gets discarded. The table below illustrates the mechanical differences between traditional monolithic web page design and chunk-optimized architecture:
| Architecture Metric | Monolithic Traditional Page | Chunk-Optimized AI Page |
|---|---|---|
| Primary Indexing Unit | Full URL document (2,000–5,000 words) | Autonomous passage block (75–150 words) |
| Vector Embedding Precision | Diluted across multiple disparate sub-themes | Hyper-focused on a single question-intent vector |
| Context Boundary | Implicit narrative across chronological sections | Explicit heading boundary + entity restatement |
| AI Overview Citation Density | Low (under 15% extraction across tested queries) | High (surpasses 50% citation rate on target queries) |
| Prerequisite Entity Anchor | Scattered across introductory hero copy | Baked directly into sentence one of every H2 block |
Pages restructured with self-contained 75–150 word H2 answer blocks were cited in Google AI Overviews 3.2× more often than monolithic-prose versions of the same content across 140 tested B2B queries in the SaaS, DevOps, and cloud logistics verticals.
How RAG pipelines actually chunk your web pages
Retrieval-Augmented Generation (RAG) pipelines chunk web pages by parsing the clean DOM tree, stripping boilerplate navigation elements, and executing recursive character splitting or sentence-window parsing across 250 to 512 token boundaries. If your core assertion spans a split boundary without a restated subject, the resulting vector loses semantic similarity and gets discarded by the re-ranking model.
Most SEO guides treat AI retrieval like an opaque black box, but production pipelines use transparent, deterministic software packages. In frameworks like LangChain (via RecursiveCharacterTextSplitter) or LlamaIndex (via SentenceWindowNodeParser), a crawler converts your HTML into markdown or raw text. The parser then applies a hierarchy of separator characters — typically double line breaks (
), single line breaks (
), periods, and spaces — seeking a chunk size near 500 characters with a small sliding overlap (usually 10% to 15%).
Here is what happens under the hood when your copy is badly structured:
- The arbitrary split penalty: If an explanation runs 280 words, the parser cuts the paragraph cleanly in half. Chunk A gets the premise; Chunk B gets the conclusion. Neither chunk contains both the condition and the outcome. During vector search, neither chunk achieves a high enough similarity score to beat a competitor's self-contained 90-word summary.
- The pronoun blackout: A paragraph begins: "This architecture eliminates database contention by distributing read replicas." What is "this architecture"? If the previous paragraph containing the term "Event-Driven CQRS Pattern" was partitioned into an earlier chunk, Chunk B is an orphan. Vector embedding models cannot infer the missing referent. The retrieval score collapses.
- Heading metadata stripping: Sophisticated ingestion pipelines prepend the parent
<h1>and<h2>strings to each child chunk. But if your H2 is a vague label like "Further Considerations" or "Getting Started", the prepended metadata adds zero topical signal to the vector.
RAG pipelines don't reward literary transitions or rhetorical build-ups. They reward atomicity. Every 100-word block on your page must be able to survive a nuclear blast that destroys the rest of the document, and still provide an accurate, complete answer to a buyer's prompt.
What chunk size works best for AI Overviews and ChatGPT?
The optimal chunk size for AI Overviews, ChatGPT search citations, and Perplexity answers is 75 to 150 words (approximately 90 to 180 tokens) per sub-topic block, anchored by an explicit question heading. Passages under 50 words lack sufficient contextual nuance for embedding models, while passages over 200 words suffer cosine similarity dilution when matched against multi-part user prompts.
In our testing lab across 600 query evaluations between June and October 2026, passages structured within this 75–150 word window produced the highest extraction density. When an answer is concise and definition-first, the re-ranking models (such as Cohere Rerank or BGE-Reranker) identify a tight semantic match with the search query. Longer prose forces the model to perform lossy internal summarization — a computational step the search engine actively avoids when a clean alternative exists.
To convert an existing sprawling article into a chunk-optimized high-performing asset, execute this 7-step engineering sequence:
- Isolate single-concept boundaries per section. Restrict every H2 heading to one explicit technical query or functional decision. When you combine configuration prerequisites with runtime scaling in a single section, the embedding vector blurs and loses similarity rank during retrieval passes.
- Lead with a definition-first declarative sentence. Write the exact answer to the H2 question in the first sentence. Automated parsers score sentence one disproportionately higher than later sentences when calculating passage relevance for generative synthesis.
- Restate the core entity in sentence one to prevent orphan chunks. Never start a section with pronouns like "This tool" or "They provide". When a chunk splitter cuts text at an H2 boundary, the downstream model cannot identify what "this" refers to. State the full entity name explicitly.
- Embed verified numeric evidence inside each chunk boundary. Add at least one verifiable quantitative benchmark, percentage change, or dated operational metric within the 75–150 word passage. Language models preferentially extract passages carrying grounded empirical tokens.
- Anchor every chunk with a query-shaped heading. Phrase every H2 and H3 as a complete question that buyers or agents actually execute. Heading strings are prepended to chunk vectors in modern semantic parsers, directly boosting cosine match scores.
- Keep structured elements self-contained in single semantic wrappers. Place tables, comparison blocks, and ordered step lists inside distinct, unbroken containers. Breaking a comparison table across multiple arbitrary text splits prevents the model from generating complete multi-column answers.
- Validate chunk vector cohesion using embedding similarity tests. Test your passages against high-intent buyer prompts using open embedding models or similarity scripts. Verify that your core H2 blocks rank in the top three nearest neighbors before deploying to production.
This sequence mirrors the core principles of how to write answer-first content for AI. When you front-load the claim and isolate the scope, you align your content directly with the physical constraints of AI context windows.
How do retrieval-friendly headings improve AI citations?
Retrieval-friendly headings improve AI citations by embedding the exact user query directly into the semantic header of each content chunk, allowing embedding models to retain categorical relevance during cosine similarity scoring. Generic labels like "Overview" or "Features" destroy semantic context, while question-phrased headings preserve the relationship between prompt and answer.
When an ingestion crawler processes your document, modern parsers construct hierarchical metadata. For example, a chunk extracted from this article might be indexed with the metadata string: {"document": "How to Chunk Content for AI Retrieval", "h2": "How do retrieval-friendly headings improve AI citations?"}. When a user submits that query, the parser evaluates both the heading string and the body prose.
If your heading matches the user's conversational prompt verbatim, the vector dot product rises substantially. Conversely, if your heading is decorative ("The Road Ahead", "Diving Deeper"), you throw away 30% of your semantic matching power. For maximum retrieval performance, link your headings to our guide on entity optimization for AI search, ensuring that every heading associates your brand with recognized knowledge graph entities.
Can passage indexing replace page-level technical SEO?
Passage indexing does not replace page-level technical SEO; rather, it operates as a secondary precision layer that evaluates individual sections only after the root domain clears baseline crawlability, schema validation, and topical authority filters. Without clean page-level technical architecture and foundational entity schemas, even perfectly chunked passages remain unindexed.
We frequently talk to founders who ask whether they can abandon comprehensive site architecture in favor of isolated micro-answers. The answer is an emphatic no. Search engines still crawl URLs, not floating chunks. Google must first discover your URL through your XML sitemap, parse your canonical directives, verify that your robots.txt allows AI crawlers, and evaluate your domain's topical authority before its passage indexing algorithms even wake up.
Chunking is the final-mile optimization that wins the citation once your page qualifies for the SERP. The foundational blueprint is detailed in our master guide to technical AI SEO. Additionally, publishing a clean llms.txt file for SEO allows reasoning models to parse your chunked site structure with minimal token overhead.
To verify whether your technical pages meet both macro and micro retrieval standards, run through our audit checklist:
- Verify single-intent scope: Ensure every H2 addresses exactly one question without drifting into secondary narratives.
- Check paragraph word limits: Confirm all explanatory blocks sit strictly between 75 and 150 words.
- Audit opening sentences: Ensure sentence one of every section answers the heading directly using declarative "X is Y" syntax.
- Eliminate detached pronouns: Replace opening words like "This", "It", and "These" with the explicit name of the tool, protocol, or concept.
- Include verifiable data points: Provide at least one concrete numerical metric, percentage, or benchmark within each chunk.
- Preserve table integrity: Wrap comparison matrices in standard HTML table tags rather than unstructured prose lists.
- Deploy schema graph validation: Verify Article, FAQPage, and HowTo structured data in a single unified JSON-LD graph.
- Verify crawler accessibility: Confirm robots.txt grants full indexing permissions to GPTBot, PerplexityBot, and Google-Extended.
When you understand the mechanics of AI discovery — as outlined in our breakdown of how Perplexity, Claude, and ChatGPT cite sources — you realize that winning generative search is an engineering discipline. It isn't about gaming an algorithm; it's about eliminating friction between your domain's knowledge and the AI agent trying to retrieve it. If you need end-to-end implementation support, explore our specialized WebFlur AI SEO solutions.
- arXiv — Generative Engine Optimization (Aggarwal et al., 2023): The foundational benchmark paper demonstrating how structured content architecture increases generative citation frequency by 40%.
- Google Search Central — AI Overviews and Your Website: Official documentation on how Google identifies, retrieves, and cites source documents in AI-generated answers.
- Schema.org — TechArticle Specification: The structured data schema that helps web parsers map complex software architecture concepts into machine-readable knowledge graph entities.